About RankLabs
RankLabs is building Automated Growth Intelligence for teams that need growth decisions grounded in evidence, not assumptions.
We start by making public-web and AI evidence inspectable.
The Evidence Gap
AI systems increasingly shape how organizations and offerings are discovered and compared. Their answers vary by provider, prompt, model, and time.
Without exact, comparable evidence, teams cannot reliably answer:
Missing Observation
Whether the organization was absent in an exact stored run
Changed Output
What changed between comparable provider observations
Evidence Boundary
Which public signals and citations were available when the answer was captured
Unknown Cause
What remains an association rather than an established cause
Many tools can show changed.
The harder question is , and whether the evidence supports an answer.
The Shift to AI-Mediated Discovery
AI is becoming part of how people research and narrow choices across industries.
A stored answer can show what a provider returned. It cannot, by itself, prove a purchase, a revenue effect, or a cause.
That creates three evidence requirements:
Availability before inference
A source must be retrievable before its representation can be assessed
Clarity before comparison
Machine-readable identity and offering signals need explicit, inspectable structure
Evidence before impact
Visibility, action, and commercial outcomes require different supporting records
The risk is not only missing visibility.
Teams can overreact to a changed answer when provider scope, public signals, interventions, and outcomes are not preserved separately.
RankLabs was built for this evidence problem.
Observe first. Resolve and explain what the evidence supports. Keep decisions, actions, and measured learning as separate governed stages.
Who Built RankLabs
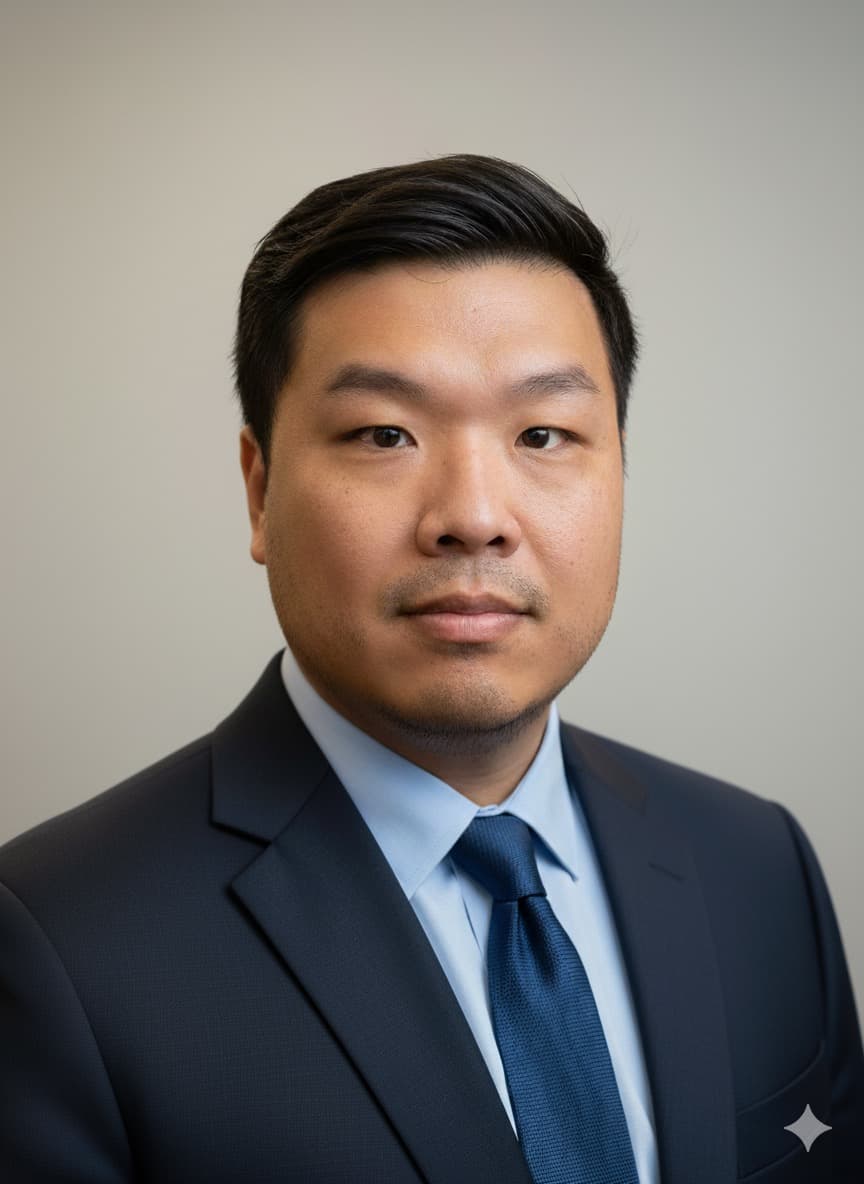
Sangmin Lee
Founder & CEO
RankLabs was founded by Sangmin Lee, an engineer who previously worked at Peraton Labs, a U.S.-based research organization supporting advanced technology programs for the Department of Defense.
Peraton Labs traces its history to Bell Labs and conducts applied research alongside public-sector technology programs, including work associated with DARPA.
In that environment, AI and machine learning systems are evaluated as components inside larger systems where correctness, traceability, and failure modes matter.
That discipline shaped RankLabs' philosophy: preserve exact inputs, expose failure modes, and prefer deterministic evidence before inference.
RankLabs applies that approach to how organizations are observed and represented across AI-mediated discovery.
Our Approach
RankLabs is built on a simple premise:
Growth decisions should be traceable to exact evidence and explicit authority.
RankLabs records what the site exposed and what enabled provider runs returned, then links the two without treating them as the same evidence:
Public-Web Evidence
Fetched HTML, entities, canonicals, structured data
RankLabs Evidence Layer
Links evidence without blending source types
Provider Observations
Stored answers, citations, provider and run context
When a stored answer changes, RankLabs can compare exact runs, citations, public-web signals, and supported gaps. It can identify evidence-backed associations and checks. It does not present those associations as proven causes without intervention and outcome evidence.
Evidence before automation.
That is the foundation for governed growth.
What RankLabs Is
RankLabs connects public-web evidence, stored AI observations, diagnostics, and governed recommendations in one platform. That is the available foundation for Automated Growth Intelligence.
Within supported scope, teams use RankLabs to:
Observe
Capture exact public-web and enabled provider evidence
Compare
Review differences between comparable stored observations
Diagnose
Surface supported structural, entity, content, and coverage gaps
Qualify
Show the source, confidence, limits, and missing evidence behind each finding
Govern
Separate recommendations, external actions, and measured outcomes
Observe and evidence-linked diagnosis are the available foundation. Cross-source decisions, customer activation, external actions, experiments, and outcome learning require separate staged authority.
How RankLabs Is Different
An output-only view can show that a stored answer changed.
RankLabs links observations to available evidence and preserves what is not established.
RankLabs can investigate an observation differs while keeping correlation separate from causality.
That distinction protects growth, product, marketing, and technical teams from acting on unsupported certainty.
Who RankLabs Is For
RankLabs is for teams that need to understand AI-mediated discovery without losing track of the evidence, including:
Growth, product, and marketing teams responsible for AI-mediated discovery
Technical and data teams responsible for source quality and evidence integrity
Organizations with products, subscriptions, services, locations, marketplaces, or sales pipelines
RankLabs is not a promise of autonomous growth, general revenue attribution, or control over provider behavior. Exact source and activation scope must be established.
Our Position
RankLabs makes evidence inspectable before decisions become actions.
RankLabs keeps crawler evidence, enabled provider observations, connected business sources, recommendations, external actions, and outcomes distinguishable.
Today, RankLabs supports observation, diagnostics, and evidence-backed recommendations. Actions and outcome learning require separate approval and measurement.
Why This Matters Now
Providers, models, prompts, sites, and business conditions change. Without exact stored evidence, teams can overreact to noise, miss meaningful differences, or attribute an outcome to the wrong intervention.
Good automation starts with knowing what was observed, what supports a finding, and what remains unknown.
Ready to build from trusted evidence?
See the crawler, AI observations, and evidence boundaries behind each supported finding.